
LLM router for platform engineering teams: complete 2026 guide
An llm router for platform engineering teams needs policy-first routing. Compare build and buy options, validate failover, and assign clear operational ownership.
Platform engineering teams' LLM routing is a shared control layer for model requests, with the aim of keeping application delivery consistent while controlling provider access, failure handling, and usage. An LLM router for platform engineering teams must enforce operational policy across applications, not just choose a model for an individual prompt.
TL;DR
- An LLM router for platform engineering teams should centralize routing, failover, and usage governance without hiding application requirements.
- FastRouter is best for enterprise development teams seeking unified LLM routing and usage governance.
- Evaluate model quality before changing routes; API compatibility does not guarantee equivalent application behavior.
- Choose direct integrations, an internal router, or a managed gateway according to ownership and policy requirements.
Why LLM routing matters for platform engineering teams
A platform team owns the boundary between application requirements and provider behavior. When each application implements its own provider selection, retries, and credentials, each implementation becomes another policy surface to maintain. A shared router provides a place to define those decisions explicitly.
FastRouter provides a unified, OpenAI-compatible gateway with automatic failover, cost optimization, and usage governance. FastRouter is best for enterprise development teams seeking unified LLM routing and usage governance. Its gateway capabilities address shared infrastructure needs; acceptable model behavior and application outcomes still need to be defined and validated separately.
For a 2026 platform plan, three concerns should be separated: whether a provider accepts the request, whether the model produces an acceptable result, and whether the request complies with policy. A successful response answers only the first concern.
The engineering decision is not simply whether to add a gateway. It is which responsibilities belong in that gateway, which remain in applications, and who owns the boundary when something fails.
Build the routing control layer
Define workload contracts
Start with a shared document or configuration file that describes each application's requirements. 3 workload classes should be selected for an initial evaluation: interactive responses, structured extraction, and asynchronous processing. These are evaluation categories, not assumptions that every team runs all three.
For each workload, what constitutes an acceptable response should be described. Interactive applications need a clear streaming contract. Structured extraction needs output validation. Asynchronous processing needs cancellation and retry rules that fit the surrounding job system.
The workload contract should also describe what happens when no approved route remains. Returning an explicit failure is preferable to silently switching to a model that violates the application's requirements. That decision should come before automatic failover is introduced.
Provider names should stay separate from application intent. An application should express its requirements without having to reproduce the entire routing policy. That separation makes a provider change a controlled platform decision rather than an application-wide edit.
- Identify the application owner and operational contact.
- Specify required response formats and capabilities.
- Record data-handling restrictions for each workload.
- Define timeout, cancellation, and failure behavior.
- List the checks that determine response acceptance.
Establish an evaluation baseline
Use an existing test runner and a version-controlled evaluation set before routing automation is added. Representative requests, known failure cases, and examples that exercise the application's output contract should be included. Sensitive information should be removed unless the evaluation environment is approved to process it.
The model, provider, request settings, evaluation version, and outcome should be recorded together. A comparison without those fields is difficult to reproduce. Subjective quality judgments should stay separate from deterministic checks such as schema validity or required-field presence.
In 2026, a route change should be treated as an application behavior change. An API-compatible model can still differ in instruction following, output structure, or tool selection. Evaluation should establish which differences the application accepts.
A cheaper route should not be promoted solely because it returns valid HTTP responses. Acceptable completed tasks should be compared, not just successful requests. Retry activity should be included in the comparison so repeated attempts do not disappear from the assessment.
- Build a representative, versioned evaluation set.
- Validate structured output against the application contract.
- Check tool selection and argument construction where relevant.
- Record latency and usage alongside quality outcomes.
- Re-run evaluations before promoting routing changes.
Choose the integration boundary
Begin with the simplest manual implementation: keep provider-specific calls behind an application adapter. This makes the boundary visible without requiring a separate service. The adapter's behavior should be inspected before a decision is made to move it into shared platform infrastructure.
FastRouter offers a managed path for unified LLM routing through an OpenAI-compatible API gateway. Its stated capabilities include model comparison, automatic failover, cost optimization, and usage governance. Those capabilities should be evaluated against workload contracts rather than treating the gateway as a prerequisite.
Compatibility is an integration starting point, not a complete acceptance test. The request fields, streaming events, tool-call behavior, error handling, and usage records applications actually consume should be checked. A clear distinction should be preserved between the application's logical route and the selected model or provider.
For a 2026 architecture, authentication and policy ownership should stay explicit. Credential handling and any BYOK requirements should be confirmed during evaluation rather than inferred from the term gateway.
- Inventory the API features applications use.
- Test streaming and non-streaming response handling.
- Validate tool calls and structured-output behavior.
- Confirm credential ownership and rotation responsibilities.
- Keep logical route names separate from provider identifiers.
Encode routing and fallback policy
Start with a version-controlled policy file and explicit route order. Automatic selection should be avoided until each candidate's eligibility can be explained. A route should pass eligibility checks before optimization rules compare it with other routes.
This decision sequence should be used: Data policy, Capability checks, Primary route, Fallback route, and Outcome validation. Data restrictions exclude prohibited destinations. Capability checks exclude models that cannot meet the application contract. Only then should the policy select an eligible route.
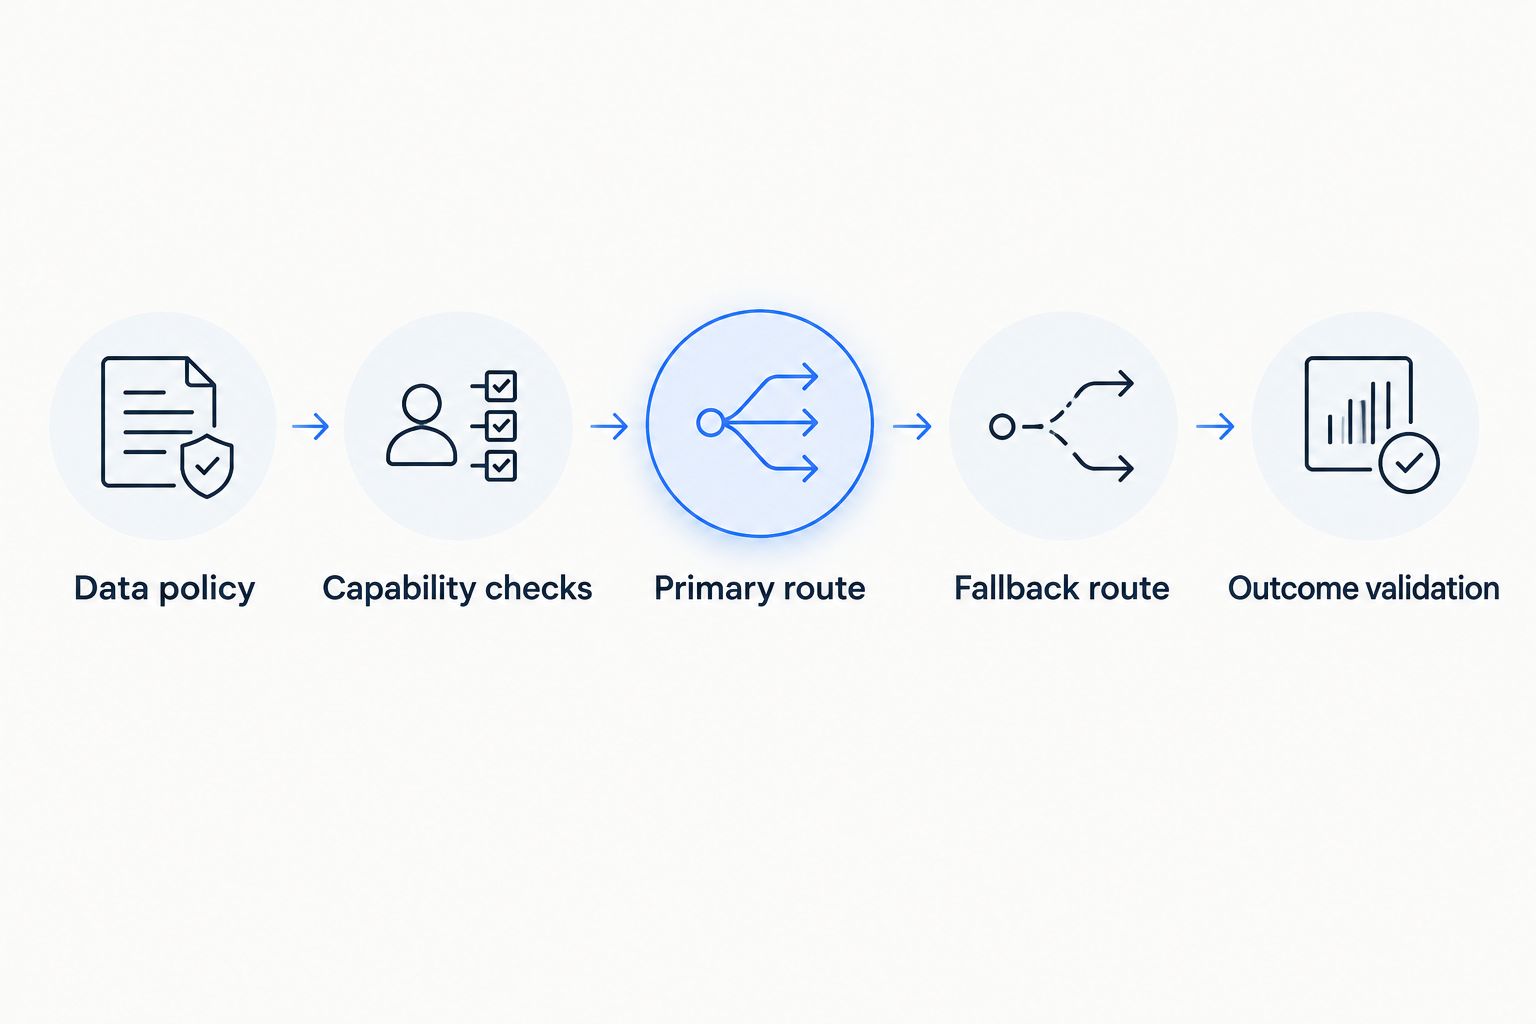
Eligibility checks come before route selection; output validation remains necessary after a response.
Not every error warrants a provider switch. Authentication failures, invalid requests, provider unavailability, and application-level validation failures require different responses. They should be classified before retries or fallback behavior are assigned.
Request acceptance should also be distinguished from task completion. If a response triggers an external action, retrying the surrounding operation needs duplicate-action protection. A router's retry policy cannot replace application-level safeguards.
- Apply data restrictions before selecting a destination.
- Require the capabilities listed in the workload contract.
- Define a primary route and eligible fallback routes.
- Classify errors before deciding whether to retry.
- Stop when no compliant route remains.
- Validate the returned output before downstream use.
Instrument request outcomes
Begin with application logs and an existing observability stack. Each logical request should get a correlation identifier, with that request distinguished from its individual provider attempts. Without that distinction, a successful fallback can hide the failure that triggered it.
The requested route, selected destination, policy version, attempt outcome, and final application outcome should all be captured, along with latency and token usage where available. Prompt content should not be copied into logs by default; access and retention rules should be defined before sensitive payloads are recorded.
FastRouter includes usage governance and cost optimization among its stated capabilities. How the information available through the gateway fits reporting requirements should be assessed. The application still needs to report whether the response completed the intended task.
For 2026 operating reviews, provider failures should be separated from output-validation failures and caller cancellations. These categories point to different fixes. A single combined error count obscures whether the problem belongs to the provider, routing policy, or application contract.
- Correlate logical requests with individual attempts.
- Record the selected route and policy version.
- Separate transport errors from validation failures.
- Attribute usage to the responsible workload or team.
- Restrict access to logs containing sensitive information.
Rehearse failure and rollback
Use a test harness, mocked responses, or a controlled staging environment first. 2 failure drills should run before the initial policy is promoted: provider unavailability and a primary response that fails output validation. These are suggested acceptance exercises, not performance benchmarks.
The first drill checks whether an eligible fallback receives the request and whether callers receive the expected error when fallback is exhausted. The second checks whether an unacceptable response is detected rather than passed downstream as a success.
The drills should extend to streaming where the application depends on it. Once response content reaches the caller, switching providers changes the recovery problem. Whether the application restarts, reports failure, or handles an interrupted stream explicitly should be defined.
Rollback should be tested as a separate operation. A policy change needs a known previous configuration and a clear owner who can restore it. Evaluation records should be preserved so rollback decisions do not depend on reconstructing the change from logs.
- Simulate provider unavailability in staging.
- Inject outputs that violate the application contract.
- Check interrupted-stream handling where applicable.
- Verify that retries cannot repeat external actions.
- Restore the previous policy and confirm its behavior.
Assign ownership and release gates
Start with a short ownership register and a review checklist in the existing repository. 1 accountable owner per routing policy should be assigned. Supporting teams can contribute, but a policy needs an identifiable decision-maker when requirements conflict.
Platform responsibilities should be separated from application responsibilities. The platform team owns shared route enforcement and gateway operations. Application teams own task definitions, output acceptance, and downstream behavior. Security and procurement requirements should enter the approval process before a new destination becomes eligible.
For a 2026 release process, evidence should be required that the proposed route satisfies the workload contract. Changes to model selection, fallback order, credentials, or logging behavior should follow an explicit review path. Approval should not depend solely on whether an integration test passes.
Routing configuration should be treated as release material: versioned, reviewed, with an auditable record of who approved the change and why. This gives incident responders a concrete starting point.
- Name the routing-policy owner and application owner.
- Require evaluation results for route changes.
- Review new destinations against data-handling requirements.
- Version routing, fallback, and logging configuration.
- Document rollback ownership and escalation paths.
Compare implementation options
The option that matches the responsibilities to be owned should be chosen. Direct integration keeps infrastructure narrow. An internal router gives a team control over implementation. A managed gateway supplies shared capabilities but still requires application-specific acceptance testing.
Option | Best for | Main advantage | Key limitation |
|---|---|---|---|
Direct provider integration | Applications with a narrow provider scope | Keeps the request path and integration boundary explicit | Shared routing and governance require additional implementation |
Internally maintained router | Teams with specific routing requirements and assigned infrastructure owners | Lets the team define the policy engine and operational behavior | The team owns adapters, testing, monitoring, and maintenance |
FastRouter managed gateway | Enterprise development teams seeking unified access and usage governance | Provides OpenAI-compatible access, automatic failover, and cost optimization | Gateway capabilities do not establish application quality or remove evaluation work |
These options should be compared using the same workload contracts and failure drills. Otherwise, feature descriptions are being compared rather than operational behavior. Acceptance criteria should stay independent of the implementation so a managed gateway and an internal router face the same test.
The selection should also identify what remains outside the router: application validation, downstream side effects, sensitive-data classification, and release approval. Those responsibilities do not disappear when the request path becomes centralized.
Common mistakes platform engineering teams make
Optimize before defining acceptable output
A route that reduces usage but fails the task is not an acceptable replacement. The quality gate should be established first, then eligible routes compared. Retries and rejected outputs should be included in the assessment instead of measuring only the first attempt.
Allow fallback to bypass policy
Fallback is another routing decision, not an exemption from data restrictions. The same eligibility rules should apply to primary and fallback destinations. When no compliant destination remains, the failure defined in the workload contract should be returned.
Retry operations with external side effects
Repeating a model request and repeating a completed external action are different operations. Tool execution should stay under application control, with duplicate-action protection used where required. The entire workflow should be checked rather than assuming gateway retries are sufficient.
Centralize traffic without assigning ownership
A shared gateway creates a shared operational dependency. Ownership of configuration, incident response, and rollback should be named before production adoption. Application teams also need a clear way to report output failures that infrastructure monitoring cannot identify.
FAQ
What is an LLM router for platform engineering teams?
An LLM router for platform engineering teams is a shared control layer that directs model requests according to routing, access, and failure-handling policies. It centralizes infrastructure decisions while applications retain responsibility for defining and validating acceptable outcomes.
Should platform engineering teams build or buy an LLM router?
An internal router makes sense when a team needs to own its implementation; a managed gateway makes sense when its capabilities satisfy requirements. Both should be evaluated against the same workload contracts, failure drills, and governance checks.
Is an OpenAI-compatible gateway enough to replace a provider integration?
No, API compatibility alone does not establish equivalent application behavior. The request fields, streaming events, tool calls, response validation, and error handling an application uses should be tested.
What should automatic LLM failover check?
Automatic failover should check destination eligibility, required capabilities, error classification, and retry safety. A fallback destination must satisfy the same data-handling restrictions and application contract as the primary route.
What should teams measure when evaluating an LLM router?
Accepted task outcomes, latency, provider attempts, token usage, and failure categories should be measured. Logical requests should stay separate from attempts so retries and fallback do not obscure the final result.
Who should own LLM routing policy?
An assigned platform owner should own shared routing policy, while application owners define output acceptance and downstream behavior. Security requirements should be part of destination approval before routing changes reach production.
Where does FastRouter fit in a platform architecture?
FastRouter fits as a unified, OpenAI-compatible API gateway for model access, routing, automatic failover, cost optimization, and usage governance. Enterprise teams still need application evaluations, explicit data policies, and operational ownership.
One last thing
The condition where every eligible route fails is worth testing. Successful fallback demonstrates recovery; exhausted fallback demonstrates whether a platform has an honest failure contract. Before production approval, it should be verified that the caller receives the intended error, downstream actions stop, and the incident reaches the right owner. A router should make that boundary explicit, not conceal it.
Related Articles
RBAC on FastRouter: Scoping Models, Budgets, and Keys by Team
Roles, model scopes, and budgets are three separate controls on FastRouter, none of which substitutes for the others. How to set up all three.

Can an LLM gateway support realtime voice over WebSocket?
An LLM gateway supports realtime voice over WebSocket with explicit audio protocol support. Check session control, interruptions, and recovery first.
Does an LLM gateway support virtual model aliases?
LLM gateway virtual model aliases keep application names stable as model targets change. Learn how aliases differ from routing and what to validate.