
Stop Paying for Tokens You Don't Need
How product teams use continuous evaluation to cut AI costs and improve output quality, with a practical 7 day playbook you can start this week.
8:00 AM PT · 11:00 AM ET · 8:30 PM IST
Save your seat
One click, register directly on Zoom. You'll get the meeting link by email right away.
Register for the WebinarNo spam. You can unsubscribe from reminders at any time.
Why evaluations matter
Most teams ship an LLM feature, watch it work in a demo, and then fly blind. Costs climb month over month, model choices are made on gut feel, and “quality” is whatever the loudest customer complaint says it is.
Evaluations change that. When every production request is logged and scored, you can answer the questions that actually drive your roadmap:
- Is a cheaper model good enough for this use case?
- Did last week's prompt change make outputs better or worse?
- Which model should handle images vs. long documents vs. chat?
Without evals, every model decision is a guess. With them, it's a score table.
Who this is for
Product Managers
Running AI features in production and wondering why costs keep climbing.
Founders & CTOs
Shipping LLM products and needing data driven model and prompt decisions.
Engineering Leads
Responsible for AI infrastructure and looking to build a measurable quality loop.
What you'll learn
Logging
Capture every request, model, tokens, cost, latency, so you have a baseline to improve from.
Custom Evaluations
Run LLM as Judge comparisons on your own production data, across chat completions, datasets, videos, and images. Replace gut feel with a score table.
Smart Evals & Fast Evals
Zero config benchmarking: FastRouter picks challenger models and surfaces the best one for your use case, with Fast Evals delivering results in minutes, not days.
What teams have achieved
Session outline
Your host
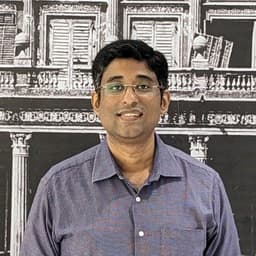
Ritesh Prasad
Ritesh leads product at FastRouter and works directly with teams shipping LLM features in production, helping them turn cost and quality guesswork into a measurable, repeatable process.
Format & details
| Duration | 60 minutes |
| Format | Online session with slides, live demo, and Q&A |
| Best for | Teams with at least one LLM powered feature in production |
Your AI costs are a product decision.
Every token you didn't need to spend is a feature you could have built instead.
Register for the Webinar